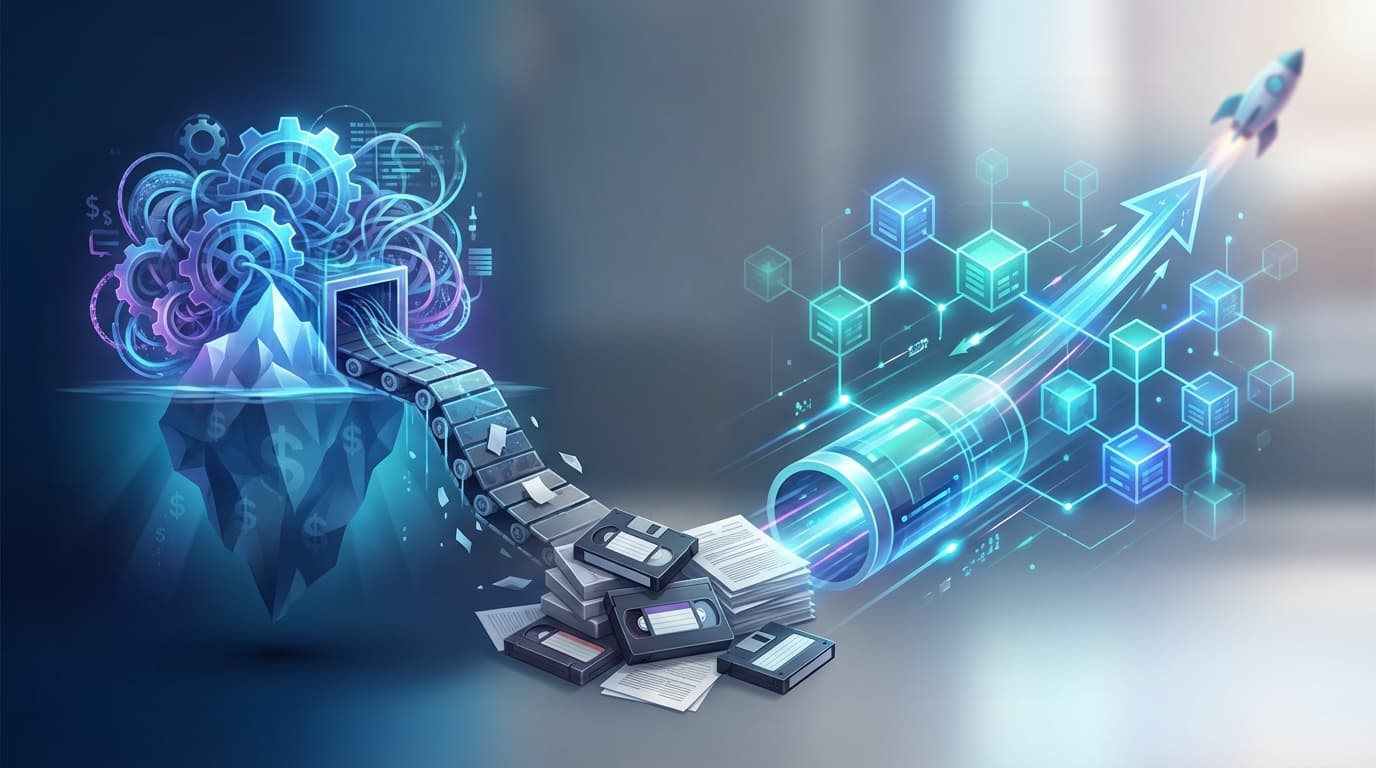
5 Hidden Costs of Manual Test Data Provisioning
Manual test data provisioning drains budgets. Discover 5 hidden costs and how test data automation saves millions. Optimize your pipeline with GoMask.
By James Walker
Co-Founder • GoMask.ai
In the modern enterprise, data is the fuel that powers innovation. Yet, for many technical leads and DevOps managers, the process of getting that fuel into the engine—test data provisioning—remains a surprisingly manual, archaic, and expensive endeavor. When we look at the budget for software development, we often scrutinize cloud spend, tool licensing, and headcount. However, there is a silent budget killer lurking in the operational shadows: manual test data processes.
Industry reports suggest that inefficiencies in test data management cost enterprises an average of $4.3 million annually. This isn't just money spent on storage; it represents a massive leak in productivity, velocity, and security posture. If your team is still relying on manual scripts, spreadsheets, or ticketing systems to move data from production to staging, you are paying a premium for inefficiency.
At GoMask.ai, we work with engineering teams who have transitioned from multi-day wait times to instant data availability. Through this work, we have identified the five most significant hidden costs associated with manual processes—and how modern test data management can eliminate them.
1. The High Price of Idle Engineering Talent
The most expensive asset in any technology company is its engineering talent. Your developers, QA engineers, and data scientists are hired to build features, fix bugs, and drive innovation. However, manual test data provisioning forces high-value employees into a state of costly idleness.
Consider the standard workflow in a manual environment:
- A QA engineer needs a fresh dataset to test a new microservice.
- They submit a ticket to the DBA or DevOps team.
- Due to backlog and complexity, the request sits in a queue.
- Result: The QA engineer waits 3 to 5 days for a database refresh.
During this 3-5 day window, context switching occurs. Developers move to other tasks, losing the cognitive thread of the feature they were working on. When the data finally arrives, they must spend hours re-acquainting themselves with the code. This "wait time tax" effectively reduces the ROI of your engineering payroll. By automating this pipeline, you aren't just saving time; you are ensuring that every dollar spent on engineering salary is directed toward active development, not passive waiting.
2. Infrastructure Bloat vs. Efficient Test Data Management
Manual provisioning almost always relies on the path of least resistance: cloning the entire production database. While this ensures data fidelity, it is a disastrous strategy for infrastructure budgeting.
If your production database is 5TB, and you have four different testing environments (Dev, QA, Staging, UAT), a manual full-copy approach means you are paying for 20TB of high-performance storage that is largely unnecessary. Furthermore, production data is often messy and redundant. Manual processes rarely include the sophistication to subset data—extracting only the relevant slice needed for a specific test case.
The Multiplier Effect
The cost isn't linear; it's exponential. As your production data grows, your non-production storage costs balloon automatically. Without an intelligent test data management solution that can subset and compress data, or generate lightweight synthetic alternatives, your cloud bill will continue to scale aggressively, offering zero additional value to the testing process.
3. The "Flaky Test" Tax: Database Masking & Quality
Manual database masking scripts are notoriously brittle. They are often maintained by a single gatekeeper and rarely updated in sync with schema changes. When a schema changes in production but the manual masking script isn't updated, the resulting test data breaks referential integrity.
This leads to the phenomenon of "flaky tests"—tests that fail not because the application code is buggy, but because the underlying data is corrupt or incomplete. The financial impact here is twofold:
- Wasted Debugging Hours: Senior engineers spend hours investigating a "critical bug" only to realize it was a data provisioning error.
- False Confidence: Conversely, bad data can lead to false positives, allowing bugs to slip into production where fixing them costs significantly more (up to 100x more than fixing them in design/dev phases).
"Data quality in non-production environments is not a luxury; it is the baseline requirement for reliable CI/CD. If your data is broken, your automated tests are worthless."
By utilizing AI-powered synthetic data generation, teams can ensure statistically accurate, referentially intact datasets that actually challenge the code, rather than breaking it.
4. The Compliance Risk Premium
In the era of GDPR, CCPA, and HIPAA, the use of production data in testing environments is a radioactive risk. Manual masking processes—often involving simple scripts that scramble names but miss complex identifiers—leave significant compliance gaps.
The hidden cost here is risk exposure. If sensitive customer PII (Personally Identifiable Information) leaks into a lower-security development environment (which is often accessible by third-party contractors or offshore teams), the resulting regulatory fines can be catastrophic. But beyond fines, the cost of remediation, legal counsel, and brand damage controls can shatter a budget.
True test data management requires irreversibility. It requires transforming sensitive data into safe, compliant assets before it ever leaves the secure production zone. Relying on manual oversight to catch every instance of PII is a gamble no enterprise should take.
5. The Opportunity Cost of Delayed Test Data Provisioning
Finally, we must address the ultimate hidden cost: the revenue you lose by not releasing faster. In a competitive B2B landscape, speed is currency. If your release cycle is two weeks long, but four days of that cycle are spent waiting for data provisioning, you are artificially throttling your company's growth.
When test data provisioning acts as a bottleneck, features sit in staging environments gathering dust. Competitors who have automated their pipelines release faster, capture market share, and close deals that could have been yours. This opportunity cost is difficult to track on a spreadsheet, but it is often the largest financial drain of all.
Transforming a Cost Center into a Competitive Advantage
The financial argument against manual test data processes is undeniable. The combination of idle engineering time, infrastructure bloat, rework caused by poor data quality, compliance risks, and delayed releases creates a multimillion-dollar drag on your operational budget.
This is where GoMask.ai changes the equation. We don't just patch the process; we revolutionize it.
The Future of Test Data Automation
By integrating GoMask.ai directly into your CI/CD workflows, you transition from a manual, ticket-based bottleneck to a self-service, automated enabler. Our platform allows you to:
- Slash Provisioning Time: Generate compliant test datasets in minutes, not days.
- Guarantee Compliance: Utilize AI-powered masking to ensure 100% GDPR and CCPA compliance, eliminating the risk of PII exposure.
- Reduce Infrastructure Costs: Create statistically accurate synthetic data or intelligent subsets, drastically reducing the storage footprint of your non-production environments.
- Empower Developers: With Git-native integration and support for VS Code and GitHub Actions, developers can pull the data they need, when they need it, without leaving their tools.
Investing in test data automation is not just an operational upgrade; it is a financial imperative. It stops the budget bleed and unleashes the full potential of your engineering team.
Stop paying the high price of manual inefficiency. It’s time to mask your data, not your potential.
Related reading
- Why Your QA Team Waits Days for Test Data (And How to Fix It)
- Test Data Management Tools: The 2025 Enterprise Buyer's Guide
- Synthetic Data vs Real Data for Testing: When to Use Each
Or skip the reading and generate a dataset — new accounts start with 25 free credits.
Share this article
Related Articles
Test Data Management as Code: Stop Waiting for Data
Eliminate data bottlenecks with GoMask. Implement TDM as code for data masking compliance and synthetic data generation. Accelerate velocity today.
April 9, 2026
Test Data Management ROI: From Liability to Asset
Stop losing millions to inefficient TDM. Discover how GoMask's test data automation and synthetic data tools drive ROI. Calculate your savings now.
April 6, 2026