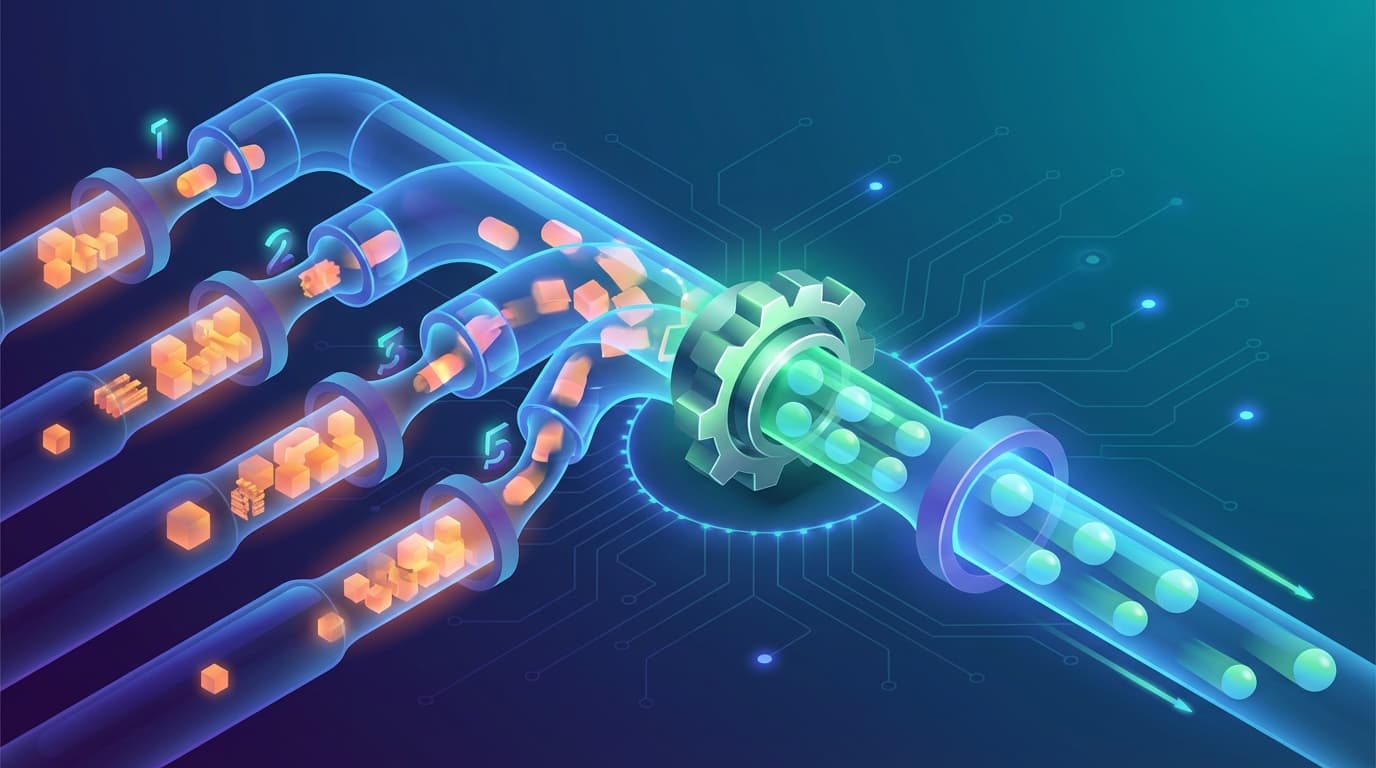
Test Data Automation: Solving 5 CI/CD Bottlenecks
Eliminate CI/CD bottlenecks with modern test data automation. Cut provisioning time and ensure compliance with GoMask. Read the full guide now.
By James Walker
Co-Founder • GoMask.ai
In the modern DevOps landscape, velocity is the primary currency. We have spent the last decade optimizing every inch of the software delivery lifecycle (SDLC). We have containerized applications, orchestrated microservices with Kubernetes, and automated infrastructure as code (IaC). Yet, despite these advancements, a massive, silent anchor continues to drag down release cycles in enterprise environments: Data.
It is a paradox familiar to almost every DevOps Lead and QA Engineer: Your build finishes in minutes, your infrastructure spins up in seconds, but your developers wait 3-5 days for a refreshed database copy to run integration tests. This mismatch is not just frustrating; it is expensive. Research indicates that inefficiencies in test data management contribute to an average of $4.3 million in annual costs for enterprises.
The reality is that traditional TDM strategies—manual provisioning, spreadsheet-based masking, and ticket-based database refreshes—are incompatible with CI/CD. You cannot have continuous delivery with discontinuous data.
At GoMask, we believe the solution lies in treating data with the same agility as code. In this post, we will dissect the five most critical CI/CD bottlenecks caused by outdated data practices and demonstrate how modern test data automation effectively eliminates them.
1. The Provisioning Lag: Waiting Days for Database Refreshes
The most obvious bottleneck is the "ticket-and-wait" workflow. In many organizations, getting a fresh dataset requires a developer to file a ticket with the DBA team. The DBAs, often overwhelmed with production stability tasks, place the request in a queue. Once they get to it, they must clone a massive production database, run manual scripts to scrub sensitive information, and finally restore it to a lower environment.
This process takes days. Meanwhile, the developer’s context switches, the feature branch goes stale, and the release window shrinks.
The Automation Solution
Modern test data automation shifts this dynamic from request-based to self-service. By integrating tools like GoMask directly into the CI/CD pipeline, data generation becomes an API call or a build step.
Instead of waiting for a full dump, developers can trigger a workflow that provisions a lightweight, compliant dataset in minutes. Whether utilizing database virtualization, subsets of production data, or AI-generated content, the result is instant availability. This capability aligns data provisioning with the speed of code deployment, ensuring that testing can begin the moment the build is complete.
2. The Compliance Gate: PII in Non-Production Environments
Security and compliance reviews are often the "Department of No" in the release process, and for good reason. Using unmasked production data in testing environments creates a massive attack surface and violates regulations like GDPR, CCPA, and HIPAA. However, traditional masking techniques are often brittle, slow, and require complex maintenance of scripts that break whenever the schema changes.
This creates a bottleneck where releases are halted for security audits, or worse, testing is done on "dummy" data that doesn't reflect production reality because the secure data wasn't ready in time.
The Automation Solution
We solve this by integrating intelligent DevOps data masking directly into the data delivery stream. Modern platforms utilize AI to automatically identify sensitive columns—PII, PHI, financial data—and apply irreversible masking techniques on the fly.
Key Insight: True velocity requires safety. By ensuring that 100% of data landing in lower environments is compliant by default, you effectively remove the compliance bottleneck. Security teams no longer need to manually audit every release because the process itself is secure.
With GoMask, this transformation happens seamlessly, ensuring that the data used for testing is statistically accurate but completely anonymized, eliminating regulatory exposure without slowing down the pipeline.
3. The Quality Trap: "It Worked on My Machine"
A major cause of failed deployments is the discrepancy between test data and production reality. Developers often write tests against stale local data or simplistic hand-coded mock data. When the code hits the staging environment (or production), it encounters edge cases, null values, or data volumes that were never simulated during development.
This leads to a cycle of deploy-fail-rollback-fix that clogs the CI/CD pipeline and frustrates engineering teams.
The Automation Solution
High-fidelity test data management bridges the gap between synthetic and production data. We leverage AI to analyze the statistical distribution and referential integrity of your production data. We then employ smart synthetic data generation to create datasets that mirror these complexities—preserving outliers and relationships—without containing real user data.
This means developers can test against "production-like" scenarios early in the lifecycle (Shift Left). By catching data-related bugs in the unit or integration testing phase, you prevent costly failures in later stages of the pipeline.
4. The Integration Silo: Tooling Mismatch
Another common friction point is the lack of integration between data tools and the developer's ecosystem. If a QA engineer has to leave their IDE, log into a separate TDM portal, manually configure a job, download a file, and import it into a local SQL instance, the workflow is broken.
Legacy TDM tools are often monolithic and disconnected from modern DevOps toolchains like GitHub Actions, Jenkins, or VS Code.
The Automation Solution
Modern test data automation must be developer-native. This means meeting the technical professional where they work. GoMask, for instance, offers out-of-the-box integrations with over a dozen major databases (SQL and NoSQL) and integrates directly into CI/CD pipelines.
Imagine a workflow where a Pull Request in GitHub automatically triggers a GoMask action. This action spins up an ephemeral database container, populates it with a fresh, masked dataset specific to that branch, runs the test suite, and tears it down—all without human intervention. This is the level of integration required to maintain true continuous delivery.
5. The Traceability Black Hole: Lack of Version Control
In code, if a build fails, we check the Git commit history. We know exactly who changed what, when, and why. In data, this history is often non-existent. If a test suite starts failing because the underlying data changed, diagnosing the root cause is a nightmare. "Who updated the staging DB?" is a question that wastes countless engineering hours.
The Automation Solution
We advocate for a Git-native approach to test data management. This involves treating data generation rules and masking policies as version-controlled artifacts.
- Versioning Policies: Store your masking configurations and synthetic data definitions in Git repositories alongside your application code.
- Reproducibility: Ensure that any dataset generated today can be re-generated exactly the same way tomorrow for regression testing.
- Audit Trails: Maintain a clear history of how data rules have evolved over time.
By bringing data definitions into version control, you achieve the same traceability for your test data as you have for your source code, eliminating ambiguity and drastically reducing debugging time.
Conclusion: Turning Data into a Competitive Advantage
The bottlenecks caused by legacy test data processes—waiting days for provisioning, navigating compliance minefields, and battling data inconsistencies—are no longer acceptable in a world that demands continuous delivery. These inefficiencies are not just annoyances; they are significant costs that erode the ROI of your DevOps investments.
By adopting modern test data automation, you do more than just speed up a process. You empower your developers with self-service capabilities, you satisfy your security team with 100% compliance, and you ensure your QA team is testing against high-fidelity, realistic scenarios.
At GoMask, we are committed to transforming test data from a stumbling block into an accelerator. Our AI-powered platform is designed to integrate seamlessly into your existing stack, enabling you to generate secure, compliant, and realistic data in minutes.
Ready to eliminate the wait? Stop letting data dictate your release schedule. Explore how GoMask can streamline your CI/CD pipeline today.
Related reading
- Why Your QA Team Waits Days for Test Data (And How to Fix It)
- Test Data Management Tools: The 2025 Enterprise Buyer's Guide
- Synthetic Data vs Real Data for Testing: When to Use Each
Or skip the reading and generate a dataset — new accounts start with 25 free credits.
Share this article
Related Articles
Test Data Management as Code: Stop Waiting for Data
Eliminate data bottlenecks with GoMask. Implement TDM as code for data masking compliance and synthetic data generation. Accelerate velocity today.
April 9, 2026
Test Data Management ROI: From Liability to Asset
Stop losing millions to inefficient TDM. Discover how GoMask's test data automation and synthetic data tools drive ROI. Calculate your savings now.
April 6, 2026